Cyberattacks on leading AI laboratories will increasingly steal or diffuse proprietary model assets
Bottom line (updated 2026-09-28): These attacks seem technically possible, and some parts of models or data can leak. But we are not sure yet that confirmed thefts from top AI labs are increasing.
What's this about?
People disagree about whether cyberattacks will increasingly steal or spread secret AI models and training data.
What supporters say
- Attackers may learn parts of training data by studying a model’s answers.
- Weak links in supply chains, software, and special computer chips may help attackers reach AI models.
- Attackers can ask a model many questions and copy some of its skills.
- Security experts treat model theft as a real and growing safety problem.
What critics say
- Most known AI attacks change or trick models, rather than steal their files.
- Public proof of theft from top AI labs remains scarce.
- People can spread a model without using a cyberattack, such as by sharing copied files.
How to read this
The number of points on each side does not show who is right; check how strong the proof behind each point is.
The bottom line
These attacks seem technically possible, and some parts of models or data can leak. But we are not sure yet that confirmed thefts from top AI labs are increasing.
The claim is that cyberattacks on leading AI laboratories will increasingly steal or spread proprietary model weights and training data. The evidence shows that this is technically possible, but does not yet show a clear rise in confirmed incidents.
The case for
Several credible attack routes could expose or reproduce valuable AI assets even when attackers cannot simply download a laboratory’s model files. Model extraction allows an attacker to query a system and use its answers to reproduce aspects of how the model behaves. Research on distributed machine-learning systems also identifies related intellectual-property risks, making unauthorized replication plausible when direct access to the weights is blocked. 1 (see Figure 1)
This does not mean an attacker has recovered a complete frontier model. But it does show that a model can be copied in part through its public or private interfaces, potentially creating measurable diffusion of its capabilities.
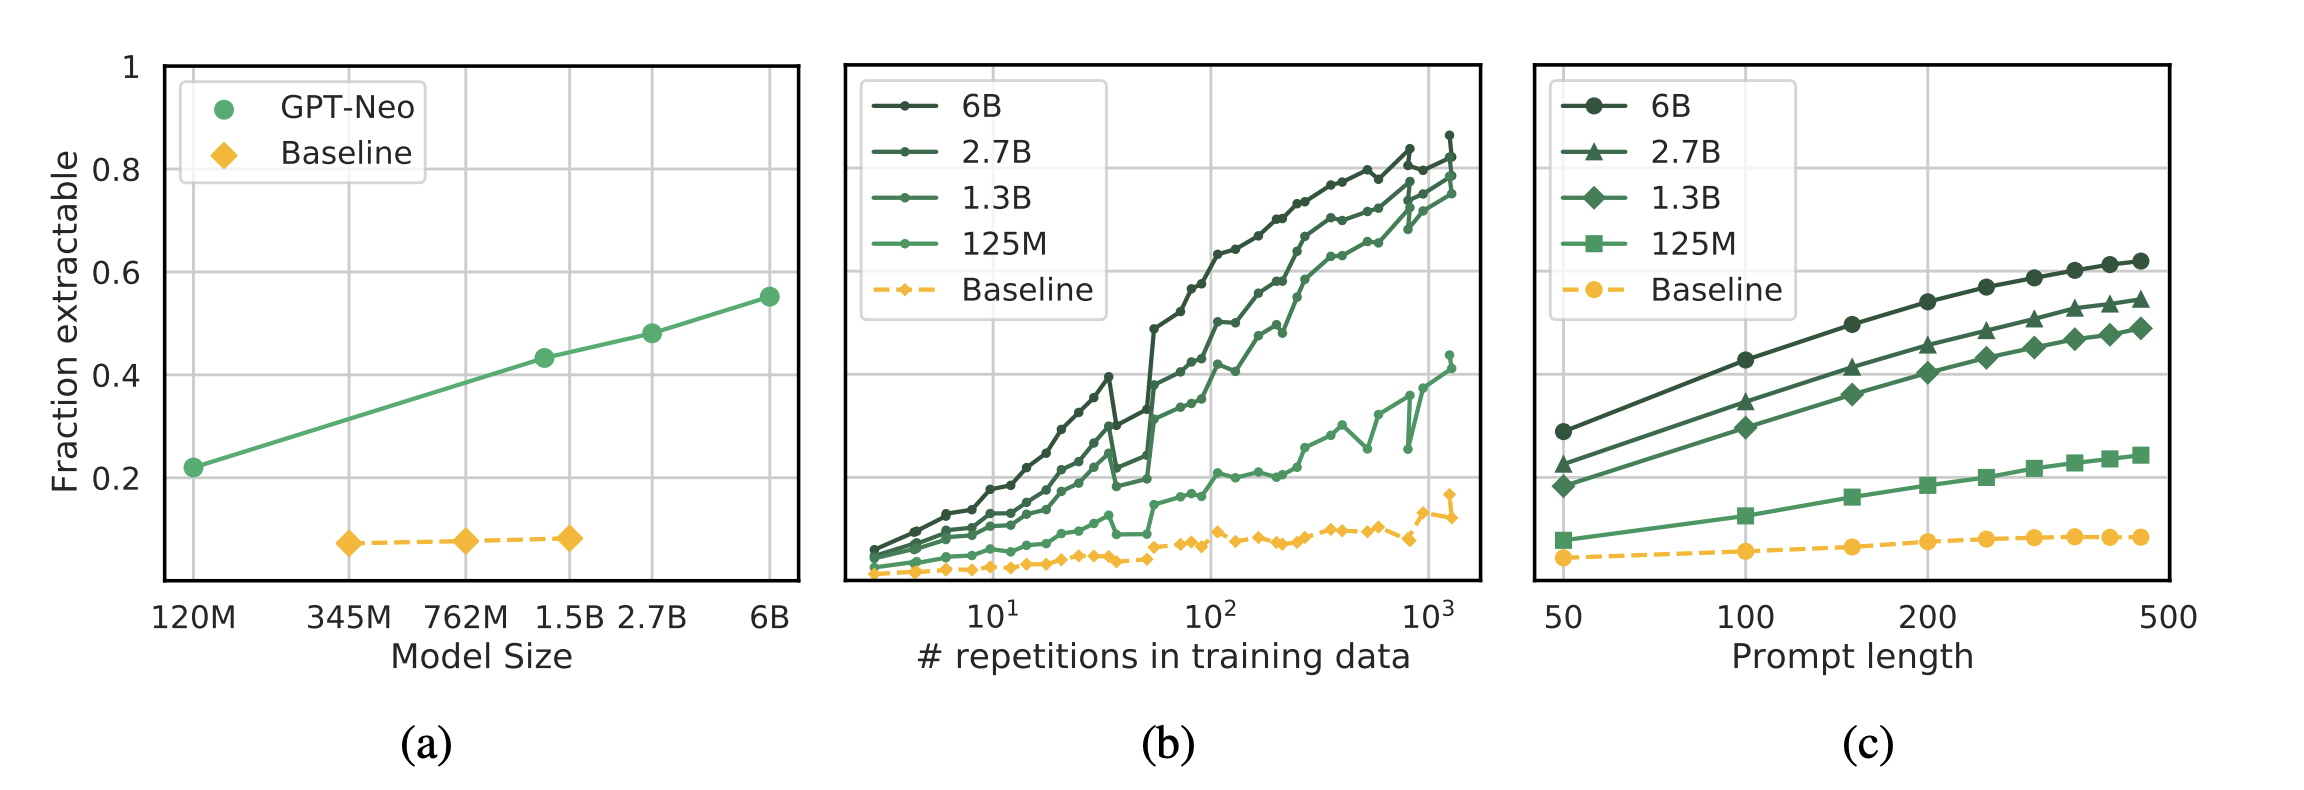
Training data can leak in a different way. Language models sometimes memorize and reproduce distinctive or repeated examples from the material used to train them. Research on foundation-model weights also explains why information encoded in those weights can carry intellectual-property value. Selective exposure of training examples is therefore a demonstrated risk, even though it is much narrower than stealing an entire training database. 2 (see Figure 2)
The surrounding technology creates additional opportunities. Supply chains, software used in training, and specialized computer hardware can all become attack points. Research describes malicious fine-tuning as one way to compromise model weights, while studies of AI accelerators identify hardware weaknesses that could help an attacker access or steal models. These findings establish plausible routes to compromise, but not confirmed theft from a leading laboratory. 3 (see Figure 3)
The existence of specialized defenses is also significant. Security researchers treat model theft and unauthorized access as active problems, particularly in distributed learning systems. That work confirms the issue is concrete rather than purely hypothetical, although it does not show how often frontier laboratories have actually been attacked. 4
The case against
The biggest problem for the claim is the limited public record of confirmed incidents. Available evidence does not establish a clear series of cyberattacks that stole frontier-model weights or complete training datasets from leading AI companies. Searches found no clearly verified public case showing that OpenAI’s frontier-model weights or training data had been stolen.
That absence does not prove that undisclosed attacks have not occurred. It does, however, weaken a forecast about an increasing trend, especially when the claim is judged by documented events rather than technical possibilities. 5
Public diffusion is also difficult to interpret. Model assets can spread through intentional releases, licensing, insider disclosures, extraction, or outside compromise. Official DeepSeek materials, for example, show that some model artifacts are deliberately released or distributed. Public availability alone therefore cannot prove cybertheft, or even identify how an asset reached the public. 6
Much of the published AI-security research focuses on manipulation, malicious fine-tuning, corrupted outputs, or adversarial behavior. Those studies show that AI systems are vulnerable and important targets, but they do not directly demonstrate the exfiltration of model weights or training data. Manipulating a model, altering its integrity, extracting its behavior, and copying its proprietary assets are different outcomes. 7
The bottom line
The evidence strongly supports the existence of technically credible attack mechanisms. Model extraction, selective training-data leakage, and compromise through supply chains or hardware could all produce unauthorized replication or exposure.
But the evidence is much weaker for the claim that theft or diffusion from leading laboratories is already increasing. There is no reliable, long-term public dataset linking attacks on those laboratories to stolen weights or training corpora. Attribution is difficult, benign releases can resemble unauthorized diffusion, and many reported AI attacks concern manipulation rather than exfiltration.
The claim is therefore more defensible if “diffusion” includes partial replication or leakage of selected data. It is less defensible if it requires confirmed theft of complete frontier models or training datasets. Overall, the evidence favours technical feasibility, but only weakly supports the prediction of a growing, measurable trend in real-world theft.
Figures & data

All contributions are reviewed for clarity, balance, and evidence. The strongest insights are elevated into the argument graph — with credit to you.
Help improve this analysis →